AI Document Processing for Distributors: Beyond OCR
When a Trading Partner Sends a PDF Instead of EDI
EDI is the clean path. An 850 purchase order or an 810 invoice arrives as structured data, maps to fields in your ERP and posts without anyone retyping it. Not every trading partner can or will send EDI, though. Smaller vendors, regional carriers and plenty of customers send PDFs because that is what their own systems produce. Turning those files into usable transactions is the job of AI document processing.
For a mid-size distributor, the result is a steady stream of documents that look different from one sender to the next: vendor invoices, credit memos, freight bills, RFQs, purchase orders, order confirmations and advance ship notices. Each one still has to become an ERP transaction. The labor cost of keying that stream by hand is covered in our post on manual document processing. Here the question is narrower: why has the usual automation fix let so many teams down?
Why Template-Based OCR Breaks on a Layout Change
This kind of OCR works by position. Someone draws zones on a sample invoice from Vendor A: invoice number here, total there, line items starting at this row. From then on, the software reads whatever text lands inside those zones on each new invoice from that vendor.
That holds until the vendor changes something. A new billing system, an extra column, a longer address block or a second page of line items pushes text out of its zones. You get blank fields or, worse, the wrong value sitting in the right field. Multiply that by hundreds of vendors and template upkeep becomes a job that never ends.
Reading by Meaning Instead of by Coordinates
An AI reader does not care where text sits on the page. It reads the way a trained clerk does. A number beside "Invoice No." is the invoice number. A table with quantities and unit prices holds the line items. "Balance Due" is the amount owed, wherever each one appears.
With no per-vendor template to maintain, a redesigned invoice is simply another layout to read. The same approach handles a supplier you have bought from for ten years and one that sent its first invoice this morning, including scanned PDFs. That is the basis of Comparatio's PDF import.
Master EDI Standards with Confidence
From ANSI X12 to EDIFACT, Comparatio handles every EDI standard so you can focus on growing your business, not managing transactions.
Request a Call
AI Document Analysis Explained for Distributors
AI document analysis covers a lot of ground. For a distributor, it has a narrow, practical meaning: taking an unstructured file and turning it into structured, checked data your ERP will accept. Three layers of technology make that happen, and vendor marketing tends to blur them together. It is worth pulling them apart before looking at specific paperwork.
In short, OCR turns pixels into text, IDP sorts that text into fields, and a large language model understands what those fields mean in context. A system built for distribution needs all three, plus the workflow that surrounds them. If your team still keys these files by hand, see why manual document processing holds distributors back.
OCR vs. IDP vs. LLM-Based Reading
- OCR (optical character recognition): converts an image or scanned page into machine-readable text. It recognizes characters but has no idea what they represent.
- IDP (intelligent document processing): software that pairs OCR with extraction and classification to pull specific fields. Older IDP tools usually depend on a template or a trained model for each layout.
- LLM-based reading: uses large language models to interpret a page by meaning, spotting an invoice number, a ship-to address or a line-item table without a predefined layout.
For distributors, the real difference is upkeep. The closer a tool gets to reading by meaning, the less you rebuild each time a supplier redesigns its forms. Comparatio's AI capabilities take this approach, so there is no template to build for each supplier.
The Document Types That Matter in Distribution
Inbound paper goes well beyond invoices. Documents that typically need to reach the ERP include:
- Vendor invoices and credit memos for AP
- Freight bills from carriers
- RFQs from customers requesting quotes
- 850 purchase orders that become sales orders
- 855 order confirmations from suppliers
- 856 ASNs (advance ship notices) announcing inbound shipments
Each one maps to its own transaction and its own team, so classification matters as much as extraction. A good system identifies what a file is before deciding where its data goes.
Scanned PDFs and Multi-Invoice Files
Two everyday wrinkles trip up simpler tools. The first is the scanned PDF: a page that was printed, signed and scanned back in is an image, not text, so OCR has to run before anything can be read. The second is the multi-invoice PDF, where a vendor batches a week of billing into one file. A capable system finds where each invoice ends and the next begins, then splits them automatically. Every invoice posts as its own transaction rather than as one muddled record. A warehouse management system with PDF import capability can handle both cases, and both are worth testing with real files during any evaluation.
Inside the Pipeline: Following One Document from Inbox to ERP
To make this concrete, follow a single hypothetical document: a credit memo from a mid-tier vendor that does not do EDI. It arrives as a scanned PDF attached to an email. Here is what a complete AI pipeline does with it, step by step.
Each stage addresses a specific failure point. Skip one and the document either stalls or, worse, posts incorrectly.
Intake: Email, Drop Folder, FTP, AS2 and HTTP
Trading partners send PDFs through whatever channel they already use, so intake has to accept several: a monitored inbox, a shared network folder, FTP transfers, AS2 connections or an HTTP endpoint. Our memo shows up by email, and the attachment is pulled automatically. Nobody forwards or downloads anything. If a vendor bundles several invoices into one PDF, the file is split into separate documents at this point.
Classification: Invoice, Credit Memo or 856 ASN?
Before extracting a single field, the system decides what it is looking at. A credit memo and an invoice can look nearly identical, yet posting a credit as an invoice reverses the direction of the money. An 856 ASN belongs with receiving, not accounts payable, much like the inbound handoffs covered in our article on order management for 3PLs. Identifying the type first sends our credit memo to the correct transaction logic.
Extraction Without Per-Vendor Templates
Next, the AI reads the page by meaning: vendor, memo number, date, referenced invoice or PO, line items, quantities, amounts and totals. Because this is a scan, OCR runs first to turn the image into text. Because no template is involved, it makes no difference that this vendor has never sent a credit through PDF import before.
Validation Against Your Own Data
Extracted fields still need checking before anything posts:
- Duplicate invoice check: has this document number already been processed?
- Arithmetic check: do line extensions add up to the stated total?
- PO line matching: do the lines tie back to an open purchase order?
- Item ID lookup: can the vendor's part numbers be mapped to your item IDs?
These are the errors that otherwise surface as month-end reconciliation headaches. Once the memo passes every check, it moves on to posting.
The Needs Review Queue
Anything ambiguous, such as a total that does not foot or an item with no match, is parked in a queue for review instead of posting. A person resolves only the exceptions while clean documents keep moving. The AI tools Comparatio runs in production are built around that split: software handles the routine reading, and your team spends its time on judgment calls rather than retyping.
Google Document AI and Other Build-It-Yourself Options
Many IT leaders researching this space end up looking at Google's Document AI service, and for good reason. It is a capable, well-documented cloud service for pulling data out of documents. For a distributor, the useful question is not whether it works. It is how much of the finished workflow the service covers and how much your team would still have to build.
That question applies to any extraction API or general-purpose model you might wire up on your own. These tools are building blocks. A distributor needs the whole structure: intake, routing, ERP validation, review and posting.
What Google Document AI Processors Do Well
Google offers several processors aimed at different jobs. Form Parser pulls key-value pairs and tables from general forms. Invoice Parser is pretrained on common invoice fields such as supplier, invoice number, dates, totals and line items. Custom Extractor lets teams define and train extraction for their own document types, and built-in OCR handles scanned images. For a development team, that is a solid foundation for reading documents.
The Gap Between an Extraction API and a Workflow
An extraction API hands back structured data. It has no knowledge of your vendors, open POs or item master. Using Document AI, a distributor usually builds:
- Intake from email, folders, FTP or AS2
- Routing logic that sends each document to the right process
- Validation against ERP records, including duplicate, PO and item checks
- A review screen for exceptions
- The integration that posts to P21, Infor SX.e or NetSuite
That is a real software project with ongoing upkeep, so distributors without developers on staff often look for a finished workflow instead. The same build-versus-buy tradeoff appears on the EDI side, covered in how MCP enables AI-powered EDI integration.
Comparison: Template OCR vs. Google Document AI vs. an ERP-Connected AI Workflow
Here is how the three approaches compare, one capability at a time:
- When a vendor changes its layout: template tools break, and someone has to rework the zones. With raw Document AI, results depend on which processor you chose and how it was trained. The ERP-connected workflow reads by meaning, so there are no per-vendor templates to rework.
- Scanned PDFs: template products usually cope through OCR. Google's service includes built-in OCR. The connected workflow supports scans too.
- Classification and routing: limited in template products. Document AI offers classification, but routing is left to you. The workflow sorts each file by document type on arrival.
- Validation against ERP data: absent from template OCR. With Document AI it becomes custom development. The finished option runs duplicate, arithmetic, PO line and item ID checks.
- Exception review: template users fall back on manual workarounds, and Document AI users create their own screen. The workflow ships with a review queue already in place.
- Posting to the ERP: template OCR needs a separate integration, and your developers write it for a Document AI build. The workflow posts directly to NetSuite, P21 and Infor SX.e.
- Ongoing maintenance: your team handles template upkeep vendor by vendor, or your developers own the custom build. With the third option, the software provider maintains it.
The third option is where a finished AI workflow differs from a raw API: the extraction is only one piece, and the checks, review and posting come with it. The PDF import workflow at Comparatio follows that third model, and the broader AI capabilities page explains how incoming files move through it.
Posting to the ERP: How Comparatio Handles P21, Infor SX.e and NetSuite
Extraction APIs stop once the text has been pulled off the page. Comparatio's AI reading is built for the step after that: getting a clean, checked record into your ERP. Documents come in over the intake channels described earlier. The system classifies each one by type, interprets it by content rather than relying on a template for each vendor, validates the contents, and then either posts the record or holds it for a person. The PDF import page and the AI overview list the specifics.
If accounts payable is your starting point, our post on vendor invoice automation from PDF covers that process step by step. This section stays focused on the ERP side.
What Lands in the ERP
Supported document types include:
- Vendor invoices and credit memos
- RFQs
- Freight bills
- 850 sales orders, 855 order confirmations and 856 ASNs
Scanned PDFs work, and a single PDF holding several invoices is split into separate documents automatically. The 850, 855 and 856 labels are EDI transaction set names. For background on how those transactions normally move between trading partners, see our guide to EDI integration for distributors.
Before anything posts, four checks run:
- A duplicate invoice check
- An arithmetic check, so the math on the document adds up
- PO line matching
- Item ID lookup
Documents that pass go straight into the ERP, whether that is NetSuite, P21 or Infor SX.e. When something is ambiguous (an item number that matches nothing in your system, or a quantity that disagrees with the PO), the document goes to a Needs Review queue instead. Someone on your team resolves it there, so nothing questionable reaches the ERP on its own.
In Production with Active Customers
This is not a prototype. The software runs today for active customers, processing their real documents. That matters if you have sat through a template OCR rollout that never settled down. A demo proves a model can read one tidy PDF. What you actually need to know is whether it keeps up with your full vendor mix, layout changes included, every working day.
Request a Call to see how Comparatio would handle documents from your own trading partners.
Questions to Ask Any AI Document Processing Vendor
Whether you are comparing finished products or scoping a build on Google's extraction service, the same questions separate a dependable workflow from a polished demo. Bring your own messiest files to every evaluation: scanned credit memos, batched invoice files and a purchase order from your least organized customer. A vendor's sample set will always look clean. Yours will not.
Keep the questions below open during each conversation. Record what the vendor actually says, not just yes or no.
Questions About Reading and Classification
- Does extraction depend on vendor-specific templates or trained layouts? Ask what happens the week a supplier redesigns its invoice. If someone has to rebuild a template, you are buying OCR with extra steps.
- How are scanned PDFs handled? Many supplier documents are printed, signed and rescanned. Test one with a skewed page or a faint stamp.
- Can it split a multi-invoice PDF automatically? Some suppliers send a month of billing in a single file. Confirm each invoice becomes its own document without manual cutting.
- Which document types does it classify? Push for specifics, and confirm it distinguishes invoices from credit memos. Posting a credit as a charge is an expensive mistake.
- Does it read PDF versions of 850, 855 and 856 transactions? Order confirmations and ship notices matter as much as invoices for inventory accuracy.
Questions About Validation, Review and Posting
- What checks run before anything posts? Look for duplicate invoice detection, arithmetic checks, matching against open PO lines, and a lookup that translates vendor part numbers into your item IDs.
- Where do ambiguous documents go, and who sees them? A review queue should hold uncertain items for a person instead of guessing.
- Which intake channels are supported? Ask whether files can arrive by email, through a watched folder, over FTP or AS2, or at an HTTP endpoint, since each one covers different trading partners.
- Does it post directly to our ERP? Name your specific system and ask to see the posted record rather than an export file.
- Who builds and maintains the integration and the review workflow? With a do-it-yourself build, that answer is usually your IT team, indefinitely.
- Is it running in production for active customers today? A roadmap slide is not the same as live volume.
Frequently Asked Questions
What is the difference between OCR and AI-based document reading?
OCR only converts an image or scanned page into machine-readable text; it has no idea what the characters represent. AI-based reading goes further by interpreting the page by meaning. It recognizes that a number beside "Invoice No." is the invoice number, or that a table of quantities and unit prices contains the line detail, wherever those appear.
Why does template-based OCR stop working when a vendor changes its invoice?
Template-based OCR reads text by position, using zones someone drew on a sample invoice from each vendor. When that vendor adds a column, lengthens an address block or switches billing systems, text shifts out of those zones. The result is blank fields or the wrong value in the right field, and keeping templates current across hundreds of vendors turns into constant upkeep.
Can AI read scanned PDFs and files that contain several invoices?
Yes, a capable system handles both. A scanned page is an image, so OCR runs first to produce text before the AI interprets it. When a vendor batches a week of billing into one PDF, the system detects where one invoice stops and another starts, then splits the file so every invoice posts as its own transaction.
What validation should happen before a document posts to the ERP?
Four checks matter most for distributors before anything posts. A duplicate check confirms the document number has not already been processed, and an arithmetic check confirms line extensions add up to the stated total. Line matching ties each line to an open PO, and an item lookup maps the vendor's part numbers to your own item IDs.
Is Google's Document AI enough to automate distributor paperwork?
Google's Document AI is a capable extraction service, but it returns structured data rather than a finished workflow. It does not know your vendor list, open orders or item master. A distributor using it typically still has to build intake from email or FTP, routing by document type, checks against ERP records, an exceptions screen and the posting integration.
What happens to a document the AI is unsure about?
Ambiguous documents are sent to a review queue where someone on your team checks them, rather than posting automatically. Common triggers include a total that does not foot, an item number that matches nothing in your system, or a quantity that disagrees with the purchase order. Only those exceptions need attention while clean documents continue into the ERP without retyping.
Table of Contents
Subscribe to the Blog
Get the latest EDI insights delivered to your inbox.
Related Articles
October 15, 2026
EDI Mapping for Distributors: From Partner Spec to Go-Live
Learn how EDI mapping works for distributors: partner specs, segments, transformation and validation rules, testing with real samples, and map maintenance.
Read More →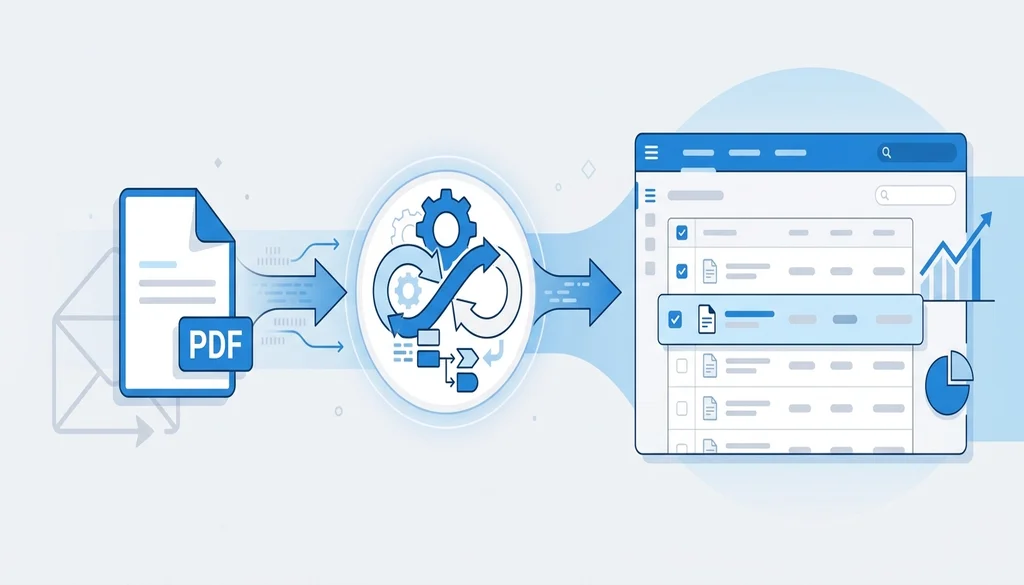
September 30, 2026
How to Automate Vendor Invoices When Suppliers Send PDFs
Suppliers who can't do EDI send PDF invoices — and someone has to retype them. Here's how to automate that without changing anything on their end.
Read More →
September 29, 2026
Amazon Epicor Prophet 21 Integration: How It Really Works
Guide to amazon epicor prophet 21 integration: SP-API and P21 interfaces, field mapping, sync timing, FBA reconciliation, options and timelines.
Read More →
Transform Your Supply Chain Today!
Ready to revolutionize your supply chain management? Our advanced software solutions are designed to streamline your operations, enhance efficiency, and boost your bottom line. Don't miss out on the opportunity to elevate your business.
Request a call